Latest Issue
Evaluation of Modified Asphalt Binders Incorporating Recycled Plastic Waste for Enhanced Pavement Performance
Published: August 31,2026An Evaluation of ANPR Technology for Traffic Violation Detection at Signalized Intersections in Phnom Penh
Published: August 31,2026Development of Eco-Friendly Microplastic Removal Filter For Sea Salt Farm
Published: August 31,2026Flood Modeling in the Lower Mekong Basin: A 2D Hydrodynamic Approach in Cambodia
Published: August 31,2026Monitoring Water Quality in Indoor Mud Crab (Scylla serrata) Farming Systems
Published: August 31,2026DEM Parameter Calibration of Biomass Materials (Sawdust, Tree Leaves, and Mixture) Using Experimental Angle of Repose Tests
Published: August 31,2026Development of Oyster Sauce Using Japanese Oysters, Green Mussels, and Clams
Published: August 31,2026Comparison of Sourdough Bread Made by Using Different Percentages of Sourdough Starter with and without Addition of Instant Dry Yeast
Published: August 31,2026Analysis of Pesticide Residues in Groundwater of Agriculturally Intensive Regions of Cambodia
Published: August 31,2026Development of Soy Sauce by Using Different Molds during Koji Fermentation
Published: August 31,2026Word Spotting on Khmer Palm Leaf Manuscript Documents
-
1. Department of Information and Communication Engineering, Institute of Technology of Cambodia, Russian Federation Blvd., P.O. Box 86, Phnom Penh, Cambodia
Academic Editor:
Received: July 17,2023 / Revised: / Accepted: August 07,2023 / Available online: June 30,2024
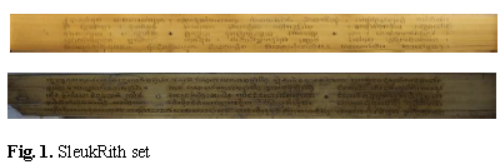
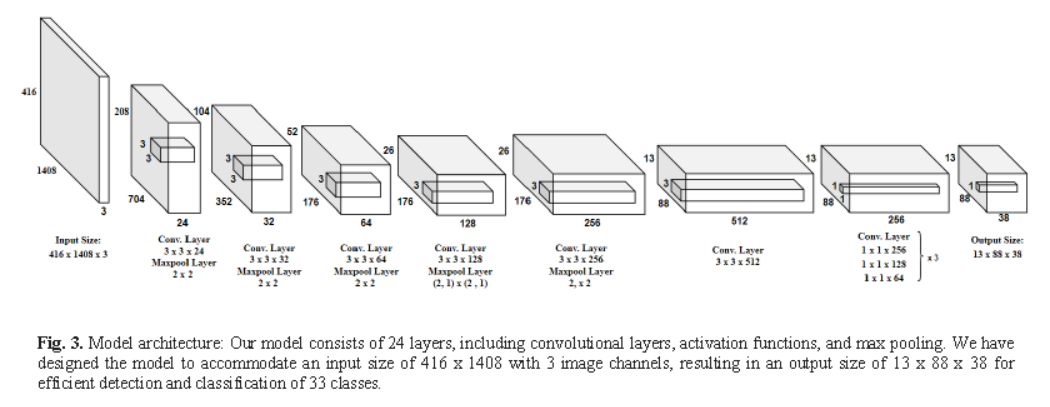
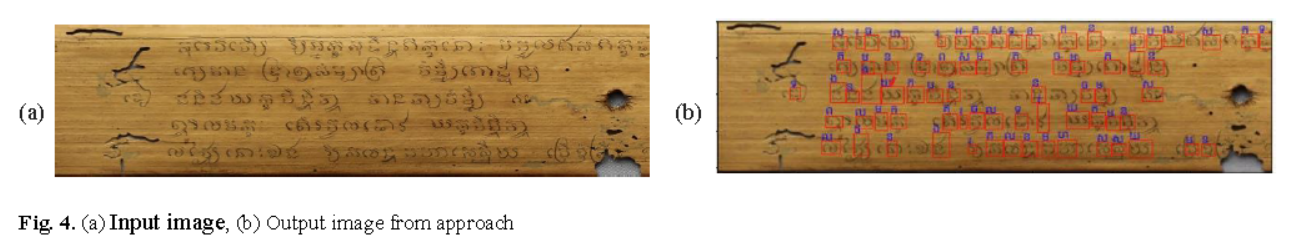
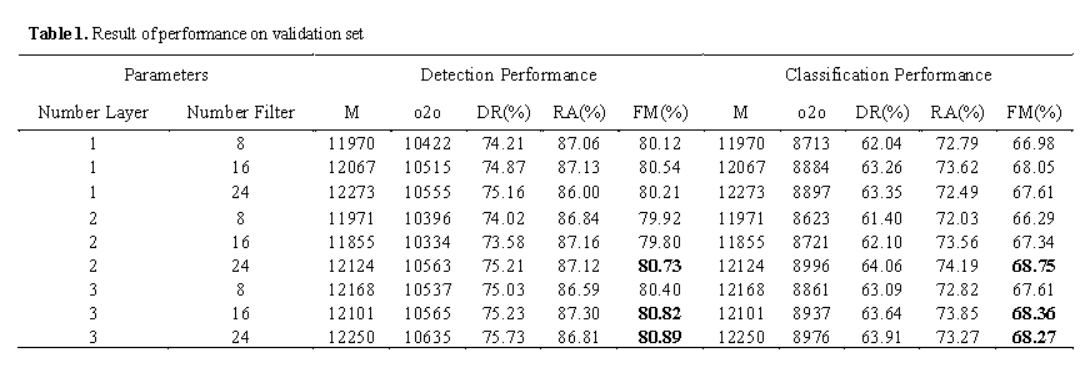
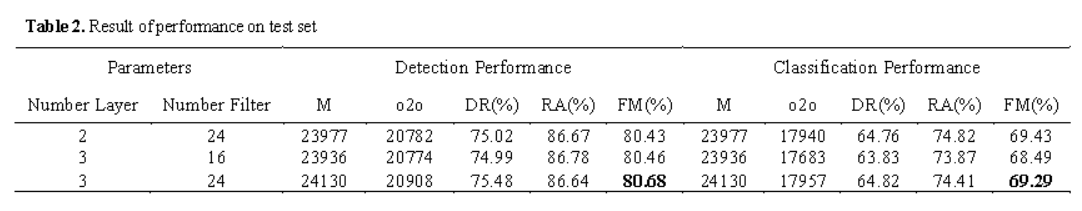
Word spotting plays a crucial role in document analysis, particularly for ancient palm leaf manuscripts. Khmer palm leaf manuscripts, which are written on rectangularly cut and dried palm leaf sheets, hold significant cultural value in Cambodia. These manuscripts contain valuable historical, religious, and linguistic information, making their preservation essential. However, extracting information from them is challenging due to their fragility, age, and the complexity of Khmer writing and word formation. This study focuses on word spotting and investigates the construction of a Region Proposal Network (RPN) using the You Only Look Once (YOLO) technique and Convolutional Neural Network (CNN) for the accurate and efficient identification of specific words or phrases within the documents. The proposed method is evaluated using the SleukRith dataset, which consists of 1,971 images of Khmer palm leaf manuscripts. Among these, 1,379 images are allocated to the training set, 395 to the test set, and approximately 197 to the validation set. Parameter tuning is conducted on two variables: the number of layers and the number of filters. The results demonstrate that the optimal model comprises 3 layers and 24 filters, with a threshold of 0.4. The achieved detection performance accuracy is approximately 80.86%, while the classification performance reaches 69.29% for the 33 classes of Khmer characters.